
What is a Kubernetes OOMKilled Error - And Why Does it Matter?
OOMKilled is a container termination reason indicating an out-of-memory kill. It is often accompanied by exit code 137, but that number alone is not a diagnosis: an ordinary SIGKILL can produce it too. Inspect the container’s terminated or last-terminated state, previous logs, events, and node conditions.
Memory headroom and resource enforcement
A memory request helps Kubernetes schedule a workload. A memory limit constrains its usage; the kernel can terminate a process when memory cannot be allocated within the effective constraints. Node memory pressure is another condition to investigate. CPU limits normally throttle execution, so high CPU utilization is not itself an OOM diagnosis. See resource enforcement and the memory-limit walkthrough.
Headroom is capacity above a measured working requirement. Observe memory over peak load, startup, large requests, and longer runs. A leak, an unbounded cache, a concurrency spike, and an undersized limit need different fixes. HPA only responds to configured metrics; it does not automatically rescue a container as soon as it reaches a limit.
Collect usage trends and runtime profiles, not just the final sample before a restart. Monitoring samples can miss brief peaks. Check each container and the node, and retain previous-instance logs before another restart overwrites the available history.
Prevention of Pod OOMKilled
Start with evidence from the affected container. Then choose a repeatable workload and monitoring setup to evaluate the suspected cause and the fix.
Inspect the failed container before changing its limits
Choose the affected namespace and pod, then inspect the available evidence:
kubectl describe pod POD_NAME -n NAMESPACE
kubectl get pod POD_NAME -n NAMESPACE -o yaml
kubectl logs POD_NAME -n NAMESPACE -c CONTAINER_NAME --previous
kubectl top pod POD_NAME -n NAMESPACE --containers
Use the real pod and container names in these commands. The status and last-state fields identify the terminated container and reason; a pod with several containers can have different outcomes for each. Previous logs are available only when the runtime retains that instance. Metrics require a working metrics pipeline and may not include the peak that preceded the kill.
Compare the recorded time with deployment changes, input size, concurrent work, startup activity, and node events. Check the configured requests and limits as well as actual usage. A CPU-heavy application such as the Kubernetes HPA example is useful for scaling experiments, but it does not deterministically demonstrate memory exhaustion. A sequential loop with a sleep also does not deliver a fixed requests-per-second rate.
For a deliberate memory-limit experiment, use the official memory-allocation walkthrough in a disposable environment. Its workload allocates memory, which directly tests the resource being constrained. Observe the actual termination state rather than assuming an HTTP load loop will produce OOMKilled.
Choose a fix from the failure mechanism
If legitimate peak usage exceeds the limit, adjust the resource budget only after checking node capacity. If retained objects grow across comparable completed workloads, inspect heap or allocation profiles. Bound caches, queues, and concurrency when those drive growth. A larger limit can delay a leak without correcting it.
Repeat the same workload after a fix and retain the result. Include a longer-duration run if growth takes time to emerge. Add alerts for memory trends and restarts so the next failure has usable evidence. There is no universal headroom percentage that guarantees availability.
Production-Ready Scenario
Use a representative workload to reproduce the conditions surrounding the failure. With Speedscale, a reviewed snapshot can supply recorded requests and dependency-response mocks. Check coverage, authentication, generated identifiers, and data state before replay. A capture preserves observed exchanges; it does not establish that every edge case or production resource condition is represented.
Run against a controlled test environment and collect memory trends alongside request rates, latency, errors, and container restarts. Confirm the generator delivered the intended load. For suspected leaks, retain runtime profiles and include enough repeated work or duration to observe retained growth. Compare the candidate fix with the same input and resource configuration.
Monitor Memory Usage with Prometheus
Prometheus can collect application and container metrics for diagnosis and alerting. Monitoring does not enforce memory budgets or relieve node pressure by itself. Use the Helm package manager to install the community chart in a test cluster:
Install Helm using its official installation instructions.
Add the chart repository:
helm repo add prometheus-community https://prometheus-community.github.io/helm-chartsNow, with minikube running, you can simply install the community version of Prometheus:
helm install prometheus prometheus-community/prometheusThis adds the required Prometheus resources to your cluster. To access the Prometheus server using the service, you should run the following command:
kubectl expose service prometheus-server --type=NodePort --target-port=9090 --name=metric-serverRun the following command to open the tab with the Prometheus server:
minikube service metric-serverThe example Prometheus targets look like this:
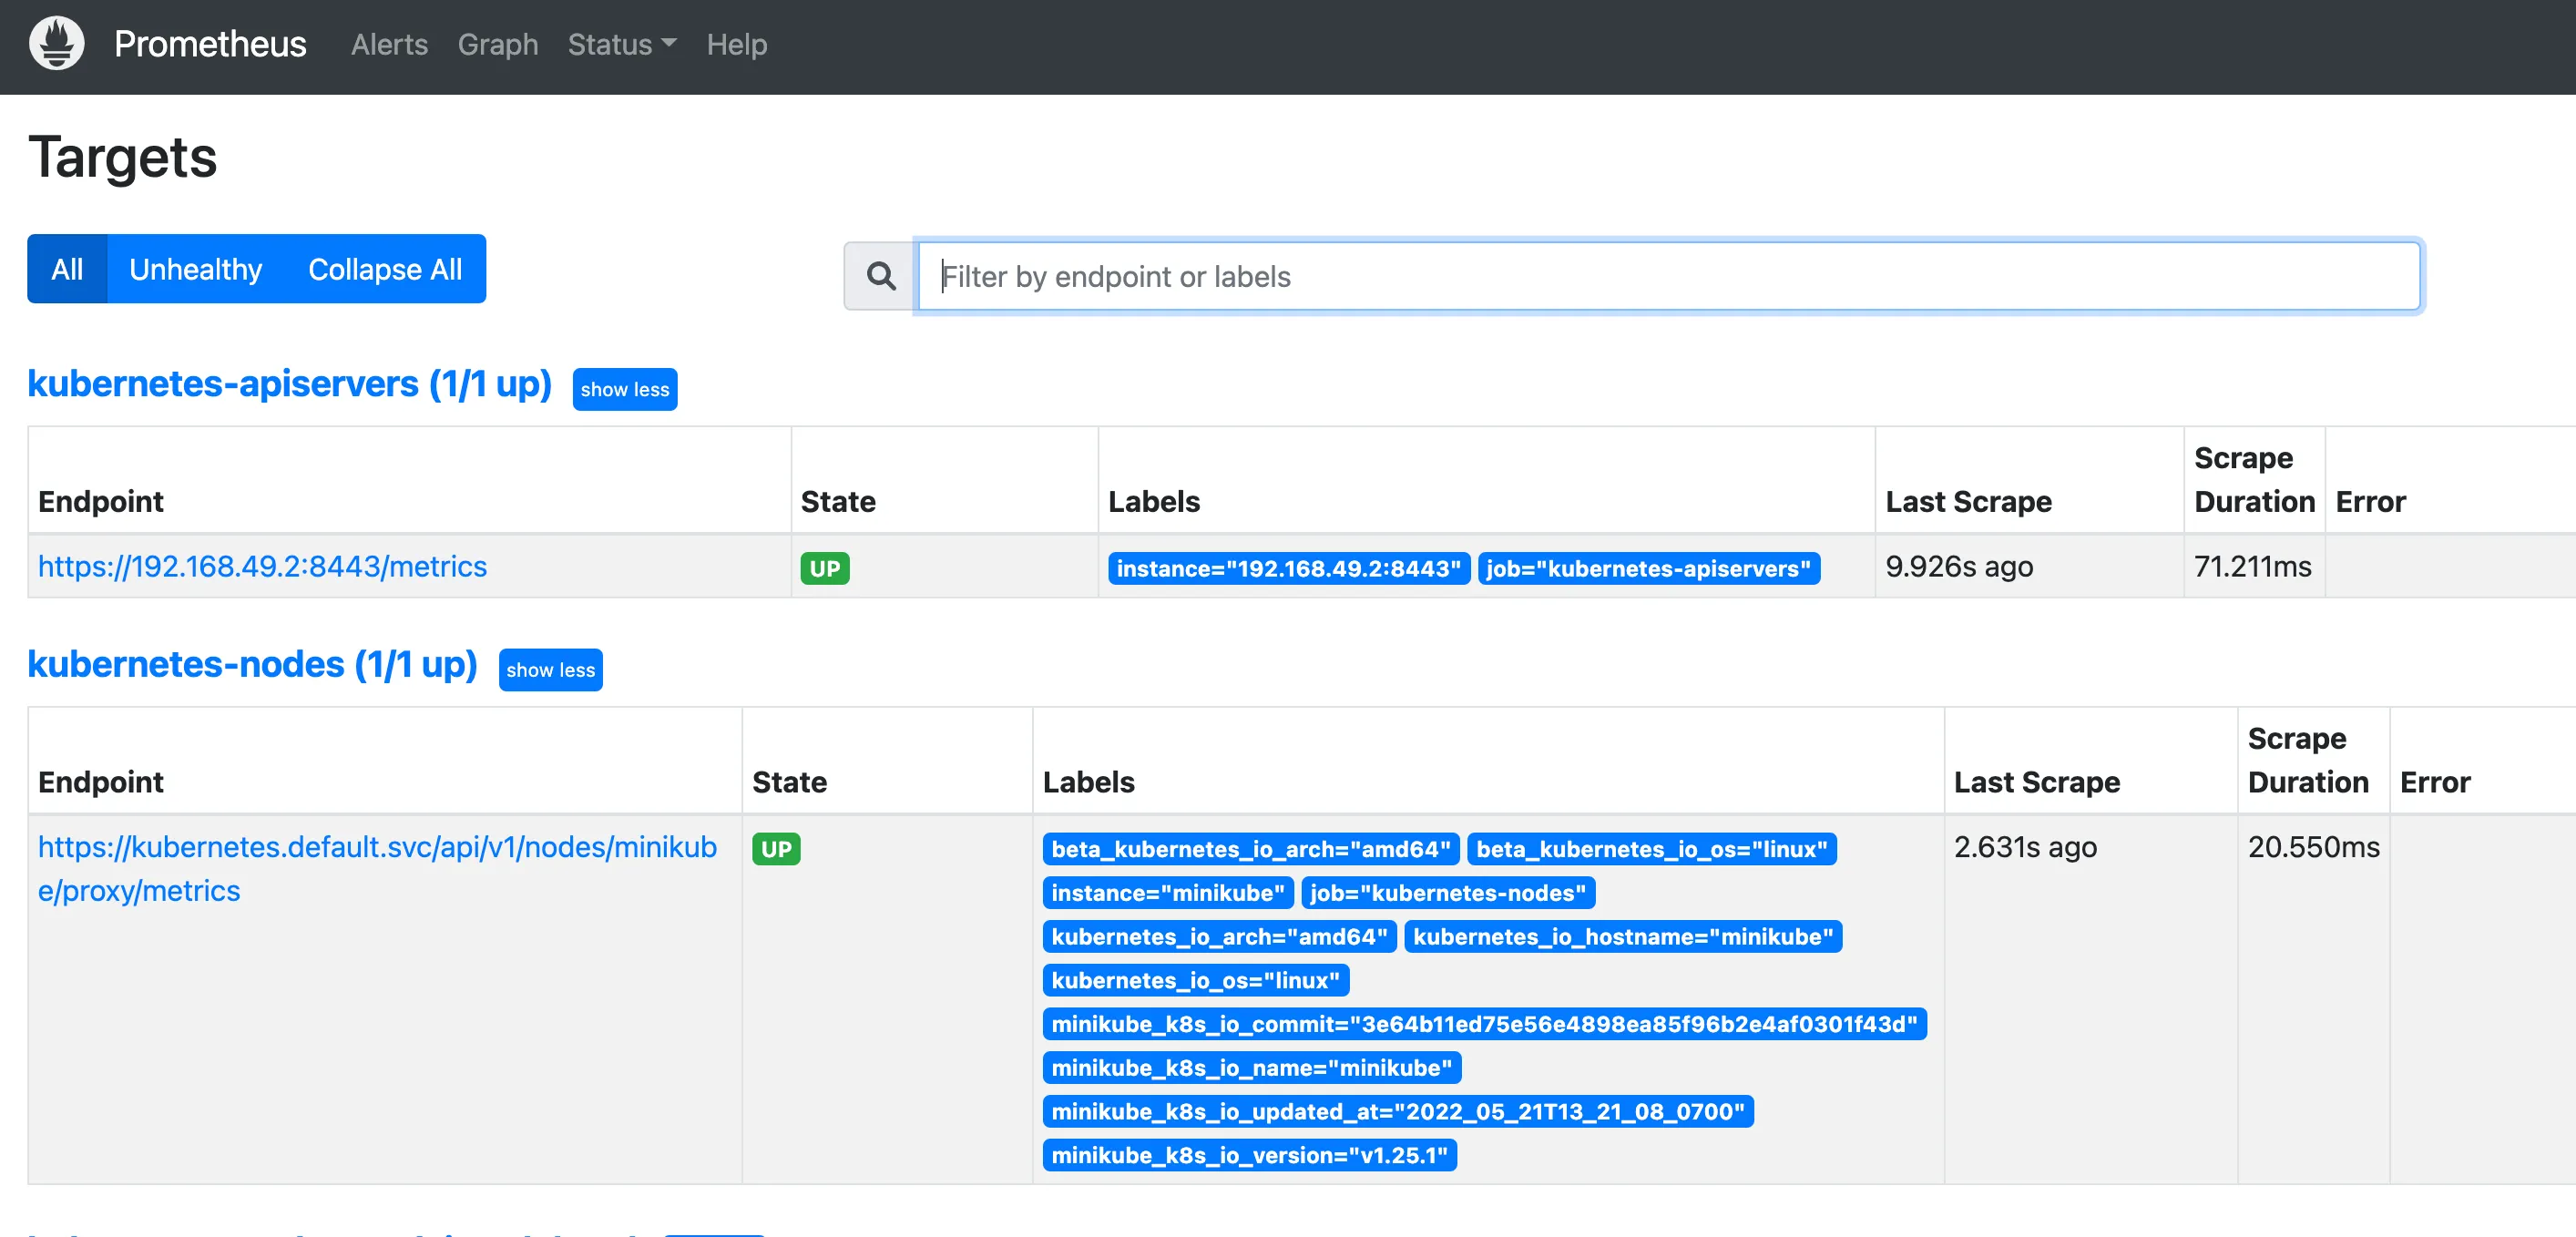
Prometheus can scrape application metrics exposed through an HTTP endpoint, such as metrics instrumented with its Go client. Grafana can query Prometheus to visualize trends. Retain historical measurements because an instantaneous query can miss the allocation spike preceding a kill.
Analysis and Decision Making
Now that you have the data about the behavior of the pod under load, you have to use this data and incorporate it into the actual production environment. When this data is limited, simple graphs help to analyze and create alerts and limits manually. However, when abundant data is available, it can be sent to a backend for collection and recording purposes. Automated analytics can be performed to derive insights about the resource provisioning required. For businesses that can accurately estimate the peak traffic for their applications, the headroom should be based on measured peak memory and observed variation. For newer businesses that can’t estimate these numbers or businesses that have incredibly variable traffic, choose a provisional resource budget, test it, and refine it from observed usage. The actual resource limits set also depend on the ability of your business to acquire the resources. Overprovisioning for a short period of time can ensure availability, and with time, analysis of production data will allow you to provision more accurately. Speedscale can also help diagnose errors and perform root cause analysis for traffic data generating errors, which makes it the ideal tool for analysis and decision-making.
Conclusion
Diagnose the termination reason before changing resources. Compare memory usage with requests, limits, workload, and node conditions, then repeat the test after a targeted fix. Speedscale can help reproduce recorded API workloads while you collect the evidence needed to evaluate memory behavior.
Frequently asked questions
Does exit code 137 always mean OOMKilled?
No. Under the usual shell convention, 137 indicates termination by signal 9, SIGKILL; an out-of-memory kill is one possible cause. Inspect Kubernetes container termination reasons and prior state, pod events, and node evidence. Distinguish an OOMKilled container from eviction or another forced termination rather than diagnosing the cause from the exit code alone.
How do I distinguish a memory leak from an undersized limit?
Compare memory over repeated, comparable workloads and after work subsides. A stable working set above the configured limit suggests a sizing issue; continued retained-memory growth can suggest a leak. Neither pattern alone proves the cause. Use runtime heap or allocation profiles, request and concurrency data, and node evidence to distinguish retained objects, caches, spikes, and memory pressure.
What evidence should I collect before increasing memory?
Save container status and restart history, previous-instance logs, relevant events, memory usage over time, requests and limits, and node pressure around the termination. Record the workload and recent changes. CPU limits normally throttle execution; they are not memory budgets. Increase a limit only with node capacity and the observed failure mechanism understood, then repeat the workload.
Sources: Shell exit-status conventions, Diagnosing container termination, Memory limits and OOM example, Kubernetes requests, limits, and enforcement.