A Developer's Guide to Improving AI Code Reliability
Improving AI code reliability starts with acceptance checks you can review and rerun. Define the required behavior, preserve the existing behavior that must remain compatible, and inspect the evidence before deploying a candidate.
Speedscale’s proxymock records API traffic and replays it against a changed application, with recorded responses available as dependency mocks. That gives a coding agent observed behavior to compare with its changes. A passing replay checks the captured scenarios and configured assertions; it does not prove every change correct or cover behavior absent from the recording.
The existing Cursor recording and replay walkthrough shows the local setup. The AI-code CI/CD tutorial supplies the runnable gate and controlled failure case. Use this guide to decide what those checks need to establish for your change.
Define reliable behavior before asking for code
A prompt such as “make this secure and performant” leaves the acceptance criteria open. State observable requirements before the agent changes the implementation. Include the inputs, expected outputs, error behavior, and compatibility constraints that matter to the application.
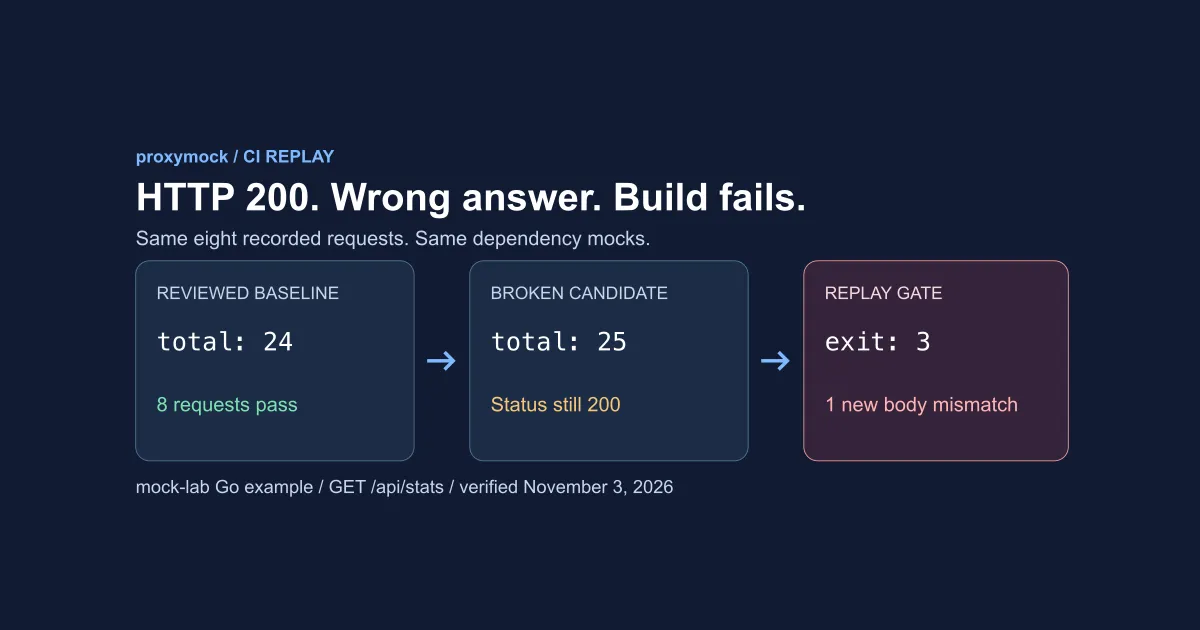
For the existing mock-lab Go app, a concrete requirement is that /api/stats returns a total equal to the project count in the accepted downstream fixture. In the controlled CI example that count is 24. Returning 25 is wrong even if the endpoint returns HTTP 200.
A request to the agent can be specific without copying an entire pipeline into the prompt:
Keep GET /api/stats compatible with the accepted project fixture.
Its total must equal the number of projects in that fixture.
Preserve the source recording, blueprint, and reviewed baseline replay.
Add a requirement-based test for the count calculation.
Run the existing replay gate against the candidate and wait for its result.
Report the candidate revision, tests run, changed responses, verdict,
exit code, and remaining behavior that the tests do not cover.
For a new endpoint or an intentional contract change, write expectations from the new requirement. The old recording can check compatibility for existing flows, but it cannot supply expected behavior for a feature it never exercised.
Match each reliability concern to a check
Use the results from each check for the question it actually answers.
| Concern | Useful check | Limit to keep visible |
|---|---|---|
| Missing functions or incompatible dependencies | Compile/type checks, installed package versions, official API references | Successful compilation does not verify business behavior |
| Incorrect calculations or boundary handling | Requirement-based unit and integration tests | Expected answers need review; generated tests can repeat the implementation’s assumption |
| Regressions in an existing API flow | Replay the preserved recording against the candidate | Coverage is limited to selected requests, assertions, and dependency responses |
| Security-sensitive behavior | Configured security scanners, targeted runtime tests, and code review | A clean scan or replay is not a complete vulnerability assessment |
| Performance or resource regression | A controlled workload, profiling, and explicit thresholds | Mocked dependencies and the test environment affect the result |
Agents with enabled tools can inspect a repository, fetch documentation, or run a compiler. Ask for the actual command output or documentation reference before accepting a claim that a dependency exists or an API is current. Tool access helps supply context; it does not guarantee correct interpretation. See the VS Code tools reference.
Preserve the evidence used for comparison
Keep the source recording separate from the baseline replay output. The recording supplies requests and recorded dependency responses. The baseline replay output shows how the accepted application version responded to that same input. The baseline parameter uses that prior replay output directory.
Run the baseline against known-good code and review the result before accepting it. Recordings can contain existing defects. Matching one of those defects only shows that the behavior stayed consistent.
Keep the recording, token-correlation blueprint, and comparison policy fixed while investigating a candidate. If the agent replaces expected responses with whatever the changed app produces, the comparison can lose the regression you wanted it to detect. Review intentional fixture updates alongside the requirement they implement.
The local walkthrough already explains capturing the Go app. Use its existing app and artifacts rather than building another sample. Review sensitive values before sharing recordings or replay output.
Verify current setup and choose the gate explicitly
Follow the installation and activation instructions, then check your installed CLI and configure the coding assistant:
proxymock version --client
proxymock mcp install
The installer detects supported MCP clients. Confirm that the tools appear in the client before starting a recording, and run from the application directory. For mock-lab’s Go app, that is languages/go. The debugging guide covers current client configuration, working-directory settings, and how to inspect failures. The MCP reference documents tool parameters.
An MCP replay_traffic call starts an asynchronous job. Follow it with list_running and read_process_logs, then inspect the completed verdict and process result. A successful tool call saying that replay started is not a passing application check.
For the saved-baseline comparison, select baseline and fail-on-new-mismatch explicitly. The corresponding CLI options are --baseline <prior-replay-output> --fail-on-new-mismatch. The CI tutorial also selects its test config and checks that all eight requests ran. A new per-request mismatch exits 3; other nonzero results can indicate failed goals or operational errors. See replay verdicts for the exact rules.
Dependency isolation also needs an explicit choice. In the checked MCP registry, mock_server_start does not expose the CLI’s --no-passthrough option. When unmatched proxied calls must fail rather than contact a real dependency, use the CLI setup in the CI tutorial and confirm that the app routes its calls through it. Calls that bypass the proxy are outside that control; starting a mock server alone does not establish network isolation.
LLM prompt for this step
Check the installed proxymock client version and install its MCP integration for my coding assistant. Discover the available tools and the existing replay gate before running a candidate. Explain the configured failure criteria and preserve the reviewed baseline.Use the existing failure case to check the boundary
The controlled example in the CI tutorial supplies a useful acceptance check. With the original source recording and blueprint unchanged, the accepted app passes all eight requests. A deliberate count error changes /api/stats from 24 to 25; the replay detects one new stable-body mismatch and exits 3. Restoring the calculation makes the same comparison pass again.
That demonstration checks a response value that a count of successful HTTP requests would miss. Its result belongs to that fixture, app revision, configuration, and runtime. It is not a benchmark of AI coding systems or proof that other application paths work.
Use the published commands and results to reproduce it. For your own change, keep the test inputs, accepted expectations, candidate revision, replay command/configuration, observed responses, verdict, and exit code together for review.
If authentication fails, first distinguish a stale recorded token from a code regression. The walkthrough’s correlation example explains carrying fresh tokens and order IDs into subsequent requests. Do not weaken application authorization to make an old token pass.
Keep security and performance acceptance separate
Security requirements need checks for the operations and attack cases relevant to the application. Use parameterized database access, appropriate input validation and output encoding, and reviewed authentication and authorization logic. A prompt requesting these practices does not enforce them.
Static analysis can detect configured vulnerability patterns, but coverage depends on its rules, language support, and available context. Keep dependency scanning, targeted runtime security tests, and review where required. OWASP describes these limits and complementary checks. An AI-assisted review can help investigate a finding; its explanation is not a security clearance.
For performance, state the workload and thresholds before running the test. Recorded requests can supply realistic inputs, but mocked dependencies change latency and remove their real capacity limits. Measurements from that setup do not predict end-to-end production capacity. Keep the runtime, resource allocation, concurrency, dependency behavior, and timing policy with the results.
After release, observe application errors, latency, and resource use against your release criteria. Investigate a change in those signals without assuming that AI authorship caused it. Preserve the inputs and regression tests that help reproduce confirmed defects.
Review the result before deployment
Require the agent to explain which checks passed, which failed, and what it did not exercise. Inspect the changed responses and test artifacts alongside the code diff. For a feature absent from the recording, require separate requirement-based tests.
If a check fails, use the debugging workflow to reproduce the problem and rerun after the fix. If the intended behavior changed, review the new expectation before refreshing the baseline. The AI code verification overview explains how replay fits into the broader process.
Run this workflow with an LLM
Give this prompt to a coding assistant with access to your project and this article. Supply environment-specific values it cannot discover.
Whole-workflow LLM prompt
Read https://speedscale.com/blog/a-developers-guide-to-improving-ai-code-reliability/ and inspect my project instructions first. Use the existing mock-lab Go example to preserve the accepted GET /api/stats project-count behavior. Keep the source recording, blueprint, and reviewed replay baseline intact; add a requirement-based count check and run the existing candidate replay gate to completion. Report the revision, changed responses, exit code, and unresolved risks. Check installed tool help before adapting commands. Report the checks actually run, their results, and anything you could not verify.FAQs about AI code reliability
Can I trust AI to write code for production?
Evaluate the candidate against your requirements and review its actual test results. proxymock can check captured API behavior, while unit tests, security checks, and integration tests address other requirements. A passing set of checks is evidence within its stated coverage, not a universal correctness guarantee.
How do I stop AI from generating unreliable code?
Give the agent concrete requirements, current interfaces, and relevant documentation. Preserve accepted behavior before it changes an existing app. Require it to run checks and show results, including failed comparisons and untested paths. Better prompts provide context; they do not replace execution or review.
What is ‘hallucinated code’ and how do I catch it?
The term can describe plausible-looking functions, dependencies, or APIs that do not exist in the required version. Check installed versions and official references, then compile or run the relevant code. Agents can assist when they have those tools, but inspect what they actually verified.
Are there risks associated with copying and pasting AI code from platforms like ChatGPT?
Generated code can contain incorrect assumptions, incompatible interfaces, or vulnerabilities. Supply the relevant application context and review the candidate before using it. Check the code and its artifacts regardless of whether it came from a chat interface, an IDE assistant, or another contributor.