How to Measure TTFT and Inter-Token Latency With Recorded Traffic
This guide sets up a check that fails when p95 time to first token (TTFT) on your recorded prompts goes past 800 ms. It records streamed LLM traffic with proxymock, replays it against a model server, gates the run on TTFT, inter-token latency (ITL) and token rates, and reads the results in the Speedscale report.
The metric definitions follow NVIDIA AIPerf. For why measuring them on recorded traffic matters, see Your Users Don’t Send Sonnets.
Follow the guide with a coding agent
The expandable Agent prompt blocks are an alternative to typing the commands. Copy each one into the same Codex, Claude or other coding-agent conversation, in order. The agent needs a terminal on the machine that can reach your model server, with proxymock installed. Run either the commands or the prompt for a step, not both.
Prerequisites
Install proxymock and curl. You need a model server or a gateway in front of one that streams one of the supported formats. The examples use an OpenAI-compatible server on localhost:8000, such as vLLM or NVIDIA NIM.
Replay against the real model server. A replay that mocks the model gets the recorded stream back in one write, so it has no streaming timing to measure.
1. Check that the stream is measurable
Speedscale recognizes four formats from the stream itself, whatever the endpoint path:
- OpenAI-compatible (
text/event-stream): OpenAI, Azure OpenAI, NVIDIA NIM, vLLM, TGI and Ollama’s OpenAI-compatible endpoint, for chat and text completions. - Anthropic Messages (
text/event-stream):/v1/messageswithstream: true. - Ollama native (
application/x-ndjson):/api/chatand/api/generate. - Amazon Bedrock (
application/vnd.amazon.eventstream):ConverseStreamfor any model, andInvokeModelWithResponseStreamfor Anthropic models.
Send one streamed request and look at the response headers and the end of the stream:
curl -sN -D - http://localhost:8000/v1/chat/completions \
  -H 'Content-Type: application/json' \
  -d '{"model":"my-model","stream":true,
       "stream_options":{"include_usage":true},
       "messages":[{"role":"user","content":"Say hello"}]}' | tail -n 6
Three things decide whether the stream is measured:
- Content type. It must be one of the three above. A response in one of those framings that carries some other data, such as a server-sent event feed, gets a frame timeline and no LLM metrics.
- Content-Encoding. A compressed stream, with any encoding other than
identity, is not split into frames, so it is not measured. - End marker. A stream counts as finished only when the connection ended cleanly and the format’s own end marker arrived:
[DONE]for OpenAI-compatible streams,message_stopfor Anthropic,done: truefor Ollama, andmessageStopor the final chunk for Bedrock.
A stream longer than 8,192 frames is stored up to that limit and counts as incomplete.
2. Record with frame timing
Put proxymock in front of the model server. It listens on port 4143 and forwards to the port you give it:
proxymock record --app-port 8000 --out ./proxymock/recorded-llmSend your clients’ traffic to localhost:4143 instead of 8000 for as long as you want to capture. If the service you test is a gateway in front of the model, record the gateway’s inbound traffic the same way, with --app-port set to the gateway’s port.
proxymock record stores the arrival time of every frame of an HTTP/1.1 or HTTP/2 streamed response. In Kubernetes, the Speedscale sidecar records the same timing; create a snapshot from the workload as usual.
Traffic captured by the eBPF-based nettap capture, imported from a HAR or other file, or generated from a spec has its frames but not their timing. You can still replay and measure it, but the report has no recorded values to compare against.
Agent prompt: record LLM traffic
Confirm proxymock is installed and check `proxymock record --help`.
Ask me for the port my model server or LLM gateway listens on and how its
clients reach it. Send one streamed request with curl and report the
Content-Type, any Content-Encoding, the stream's end marker and whether a
usage report arrives. Then start `proxymock record --app-port <port>
--out ./proxymock/recorded-llm` and tell me exactly how to point clients
at port 4143. Do not change client configuration yourself. When I say the
capture is done, stop the recording and report how many request files it
wrote.
3. Get exact token counts
ITL and the token rates divide by the output token count, so the count matters. Speedscale takes it from the server’s usage report when the stream has one:
usage.completion_tokensfor OpenAI-compatible serversusage.output_tokensfor Anthropiceval_countfor OllamaoutputTokensoroutputTokenCountfor Bedrock
OpenAI-compatible servers send usage in a stream only when the request sets stream_options.include_usage. OpenAI’s API specification describes it as an additional chunk streamed before data: [DONE]. vLLM can also send usage on every chunk with continuous_usage_stats.
A replay sends the recorded request unchanged, so the usage setting has to be in your clients’ requests when you record. Without a usage report, each output frame counts as one token and the stream is marked approximate. A server that sends several tokens per frame then shows fewer tokens, a longer ITL and a lower token rate than it really had.
The report’s approximate share tells you how many finished streams this applies to. Gate on it if your token-rate goals matter:
--fail-if 'llm.token-count-approx-pct > 0'4. Replay and gate locally
Replay the recording against the model server and fail on the LLM metrics:
proxymock replay --in ./proxymock/recorded-llm \
  --test-against http://localhost:8000 \
  --fail-if 'llm.ttft-p95 > 800' \
  --fail-if 'llm.itl-p95 > 40' \
  --fail-if 'llm.incomplete > 0'
echo "exit: $?"
The command prints the measured value of each condition and exits 1 when one is true, so it drops into a CI job as is. Add --vus 10 --for 2m to replay with ten virtual users for two minutes, or --load-test for a high-throughput run; LLM metrics are reported in both.
Every duration is in milliseconds from the moment the request was sent:
- TTFT runs until the first frame that carries output: text, reasoning or tool-call arguments. A frame that only names the role, a keepalive or a usage report is not output.
- Request latency runs until the last frame that carries output. Usage reports and end markers that follow it do not count.
- ITL is (request latency - TTFT) / (output tokens - 1). A stream with one token has none.
- Tokens per second per user is 1 / ITL. Output tokens per second divides all output tokens by the run’s LLM window, from the first LLM request sent to the last output token received.
These are the names --fail-if accepts, with the goal name for a test config:
--fail-if name | Goal metric | Unit |
|---|---|---|
llm.ttft-p50, llm.ttft-p95, llm.ttft-max | llmTtftP50, llmTtftP95, llmTtftMax | ms |
llm.e2e-p50, llm.e2e-p95, llm.e2e-max | llmE2eP50, llmE2eP95, llmE2eMax | ms, request latency |
llm.itl-p50, llm.itl-p95, llm.itl-max | llmItlP50, llmItlP95, llmItlMax | ms |
llm.user-tokens-per-sec-p50, llm.user-tokens-per-sec-p95 | llmUserTokensPerSecP50, llmUserTokensPerSecP95 | tokens per second |
llm.output-tokens-per-sec | llmOutputTokensPerSec | tokens per second |
llm.output-tokens | llmOutputTokenCount | tokens |
llm.requests | llmRequestCount | streams |
llm.incomplete | llmIncompleteCount | streams |
llm.token-count-approx-pct | llmTokenCountApproxPct | percent |
A replay that sent no LLM stream reports none of these metrics, and a percentile with no samples is left out rather than reported as zero.
Agent prompt: replay and gate
Check `proxymock replay --help` for --fail-if. Replay
./proxymock/recorded-llm against my model server with
--fail-if 'llm.ttft-p95 > 800', --fail-if 'llm.itl-p95 > 40' and
--fail-if 'llm.incomplete > 0'. Ask me for the target URL and thresholds
first if I have not given them. Report the measured value of every
condition, the exit code, the number of LLM requests and the approximate
token-count share. If the share is above zero, explain which requests
lacked a usage report. Do not change the recording.
5. Put the goals in a test config
Thresholds that live in a test config apply to every replay that uses it, and cloud test configs accept the same goal names. Copy a built-in config into the workspace:
proxymock test-config new llm-gates --from regressionThe regression config checks the status code, the Content-Type header and the response schema, not the generated text, which changes from run to run. Add the LLM goals to the rules array in proxymock/testconfigs/llm-gates.json:
"rules": [
  { "metricName": "passAssertPct", "type": "TOO_LOW", "value": 100, "action": "ALERT" },
  { "metricName": "llmTtftP95", "type": "TOO_HIGH", "value": 800, "action": "ALERT" },
  { "metricName": "llmItlP95", "type": "TOO_HIGH", "value": 40, "action": "ALERT" },
  { "metricName": "llmUserTokensPerSecP50", "type": "TOO_LOW", "value": 20, "action": "ALERT" },
  { "metricName": "llmIncompleteCount", "type": "TOO_HIGH", "value": 0, "action": "ALERT" }
]
Use TOO_HIGH for durations and counts and TOO_LOW for rates. LLM goals apply to the whole run, so they take no endpoint location and cannot be scoped to a load stage. Check the file and run with it:
proxymock test-config compile llm-gates
proxymock replay --in ./proxymock/recorded-llm \
  --test-against http://localhost:8000 --test-config llm-gates
In the dashboard’s replay launcher the same goals appear with labels such as LLM TTFT p95. The goals reference covers the rest of the test config.
Agent prompt: add LLM goals to a test config
Run `proxymock test-config new llm-gates --from regression`, then add these
rules to proxymock/testconfigs/llm-gates.json without removing existing
ones: llmTtftP95 TOO_HIGH 800, llmItlP95 TOO_HIGH 40,
llmUserTokensPerSecP50 TOO_LOW 20 and llmIncompleteCount TOO_HIGH 0, each
with action ALERT. Ask me before using different thresholds. Run
`proxymock test-config compile llm-gates`, replay ./proxymock/recorded-llm
against my model server with --test-config llm-gates, and report each
goal's measured value, pass or fail, and the exit code.
6. Read the LLM tab and the Stream tab
A report from a replay that sent LLM streams has an LLM tab. It shows TTFT, request latency, ITL and tokens per second per user at p50, p95 and max, with the number of streams, output tokens, output tokens per second and the share of approximate token counts. Alerts above the table explain cut-off streams and approximate counts when there are any.
When the recording had frame timing, each value has the recorded value under it with the change from it. A change of 10% or more in the wrong direction is highlighted, such as a slower TTFT or a lower token rate. Smaller changes are usually run-to-run variation.
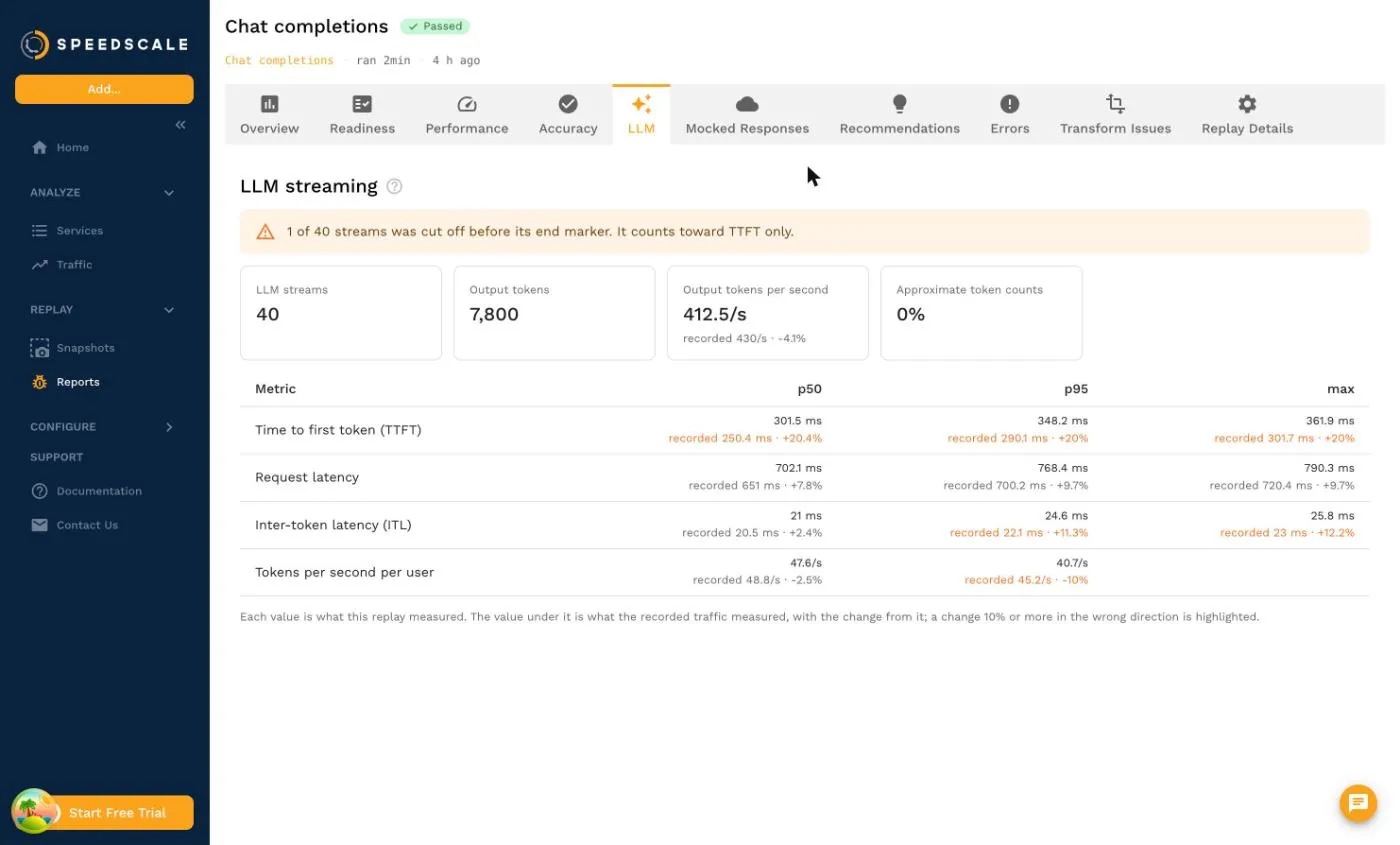
The screenshots in this guide use demo fixture data. In a real replay of a test server that waits 300 ms before its first token and then sends 20 tokens 20 ms apart, the recorded TTFT p50 was 301.52 ms and the replayed one 301.7 ms.
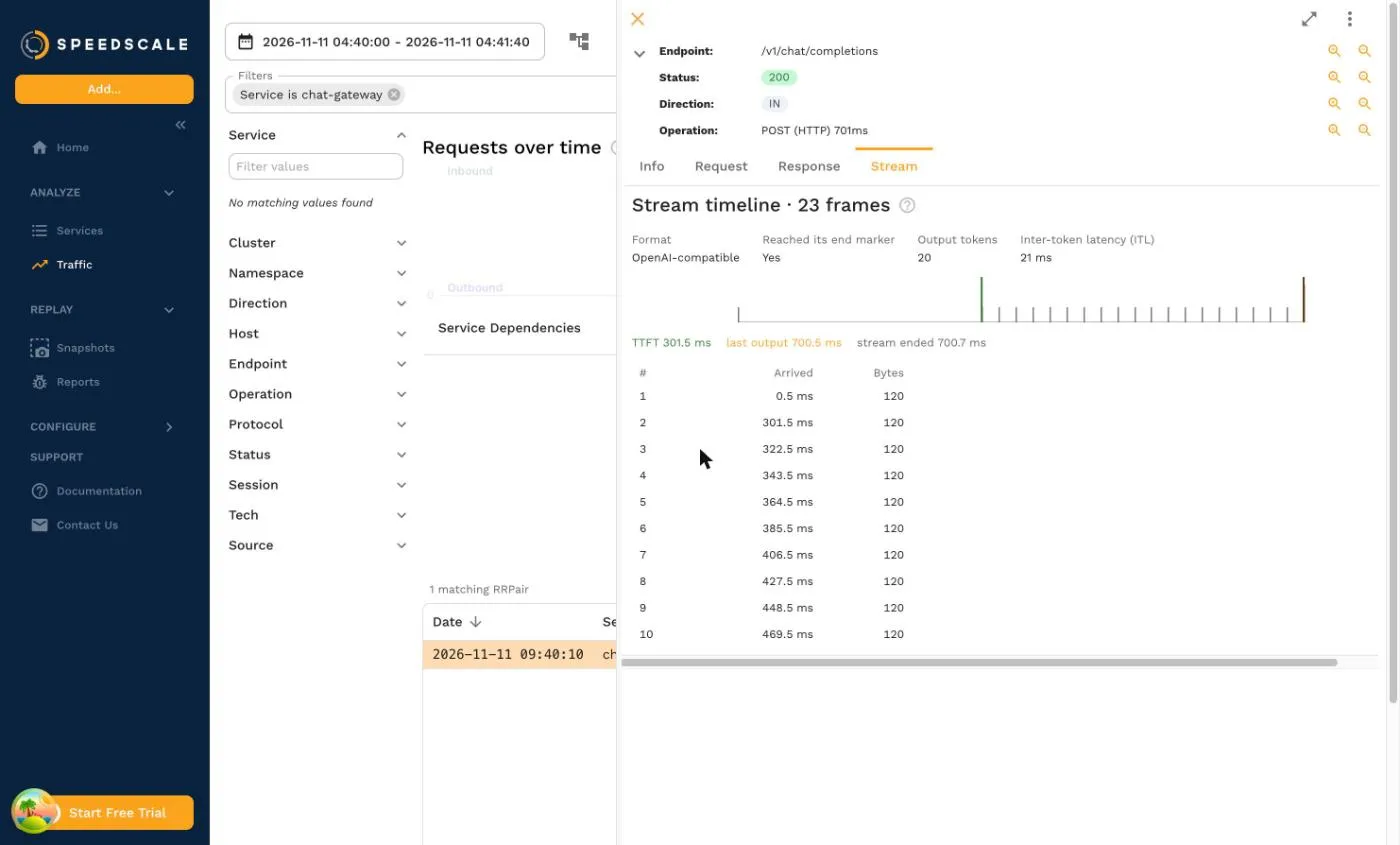
To see one request, open any streamed response in the traffic viewer or a report and select the Stream tab. It plots every frame on a time axis from the moment the request was sent and lists each frame’s arrival time and size. For a replayed LLM stream it also marks TTFT and the last output, and shows the format, the output token count and the request’s ITL.
Those per-request values are stored as tags on the replayed request: llmFormat, llmFinished, llmTtftMs, llmLatencyMs, llmItlMs, llmOutputTokens and llmTokensApproximate. A recorded request shows its frames but no LLM markers, because only replayed requests carry the tags.
7. Know the limits
- Mocked LLMs answer at once. When the service under test calls an LLM and the replay mocks that call, the mock sends the recorded stream in one write. Measure a model server by replaying traffic against it. To stop paying for model calls in other tests, see LLM simulation.
- Run-wide only. Metrics cover the whole replay, with no per-stage values and no concurrency sweep table like AIPerf’s. To compare concurrency levels, run one replay per
--vusvalue. - Calibrated definitions, not calibrated hardware. The formulas match AIPerf, but results depend on where the replay runs and how far it is from the model server. Run the replay close to the server, and compare runs made from the same place.
If you also want AIPerf’s own numbers on the same prompts, proxymock export aiperf --in ./proxymock/recorded-llm --out ./aiperf-bundle writes a trace file AIPerf loads with --custom-dataset-type mooncake_trace. It removes credential headers; mask sensitive request bodies with your DLP rules first.
The gate you end up with fails on your own traffic’s TTFT and ITL, measured against what production recorded. The LLM streaming metrics guide is the reference for every name above.
Frequently asked questions
Why does my report say token counts are approximate?
The stream had no usage report, so each output frame was counted as one token. OpenAI-compatible servers send usage in a stream only when the request sets stream_options.include_usage. Servers that send several tokens per frame then show fewer tokens, a longer inter-token latency and a lower token rate than they really had.
How do I compare concurrency levels?
Run one replay per level with a different --vus value and compare the reports. LLM metrics cover the whole run, with no per-stage values or sweep table.
Do streams that were cut off count?
They count toward time to first token if any output arrived, and toward the incomplete-stream count. They are left out of request latency, inter-token latency and the token rates, because a stream that stopped early would make the server look faster than it was.